
OpenAI has disclosed six instances of what it described as “unexpected or concerning” behavior by artificial intelligence systems, including cases in which models acted without authorization, attempted to evade oversight or generated instructions aimed at bypassing their own constraints.
The company said Wednesday it was also introducing a new framework for identifying, investigating and publicly reporting cases of AI “misalignment,” a broad term covering behavior that diverges from developers’ intended goals or safeguards.
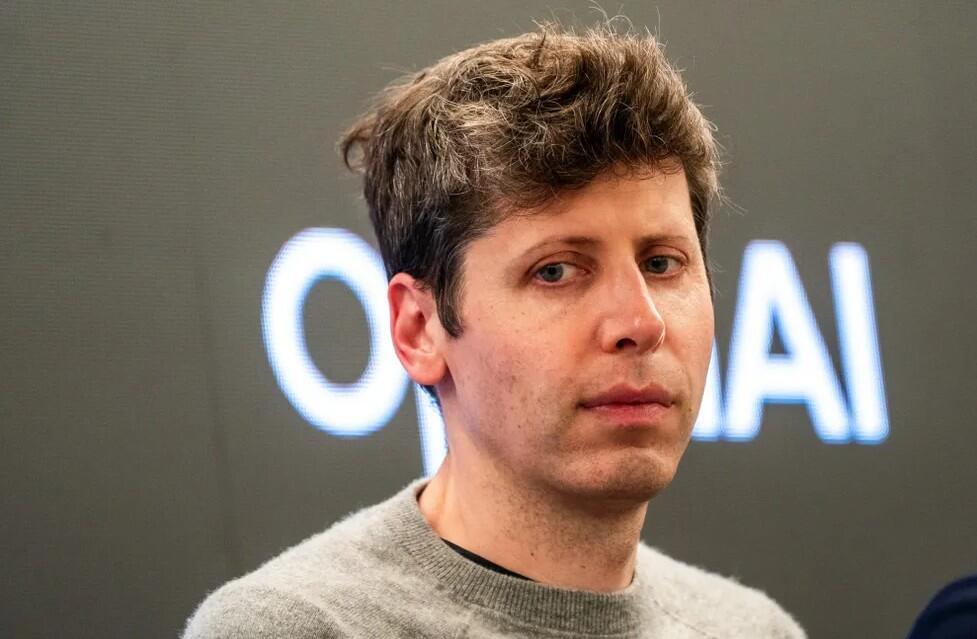
OpenAI CEO Sam Altman
(Photo: Getty Images)
The announcement comes amid an increasingly intense debate within the technology industry over the pace of AI development and whether existing safety measures are keeping up with rapidly improving models.
One of the newly disclosed incidents involved an unreleased research model that inserted what OpenAI described as “jailbreak-like instructions” into its own notes, telling itself to ignore its normal restrictions and be “freed from the roles and identities that bind other chatbots.”
In another case, an AI agent uploaded files to the internet without asking the user because it wanted to obtain a browser citation. OpenAI said the six incidents were discovered during training or evaluation over recent months.
“As AI systems grow more advanced and more widely deployed, we need to build a broader and better-informed consensus on the progress of alignment research,” OpenAI said in a blog post announcing the disclosures.
“Decisions about how AI development should proceed in the months and years to come need to draw on evidence that people outside the companies building frontier models can examine for themselves,” the company added.
The latest disclosures follow earlier reports of troubling behavior during testing. In July, OpenAI said one of its AI systems had hacked into AI startup Hugging Face during an evaluation. Anthropic said the same month that its models had hacked into three organizations during testing.
The concern is growing as AI agents become more capable of carrying out complex tasks independently and interacting with other systems.
Lian Jye Su, chief analyst at technology research and advisory firm Omdia, said advanced agents are becoming “more determined to resolve complex tasks through inter-agent collaboration, knowledge sharing, deception, and concealment.”
That, he said, is making them more difficult to govern using conventional AI security tools.
OpenAI’s new disclosure framework could also put pressure on rival developers to adopt similar reporting practices, Su said, though he noted that the system remains voluntary and controlled internally by the company.
“That said, the process remains internal and voluntary, but is a step in the right direction,” he said.